Originally published at maturitylab.com. This text belongs to the track Maturity.
An observability maturity model describes, in levels, how an organization develops the ability to understand how its own systems behave in production: from the alert raised by a customer complaint to the investigation of new failures with data collected by design. The model serves two purposes. First, it shows the current level based on evidence. Second, it points to the practices needed for the next step. This article presents the reference concepts, a level scale, the signs of each level and a step-by-step guide to the assessment.
Monitoring and observability are not the same thing
The DORA research program, which studies the performance of technology teams, separates the two concepts. Monitoring is the tooling that lets a team watch and understand the state of its systems based on conditions defined in advance. Observability is the tooling that lets a team actively debug the system by exploring properties and patterns not defined in advance (dora.dev).
The difference determines the maturity level. Monitoring answers known questions: is the server up, has the queue passed its limit. Observability answers questions nobody anticipated: why one group of customers saw slow responses yesterday at 3 p.m.
The OpenTelemetry project, hosted by the Cloud Native Computing Foundation, describes the same idea: observability lets you understand a system from the outside by asking questions without knowing its inner workings. For that, the application must be instrumented and emit signals such as traces, metrics and logs (opentelemetry.io).
The levels of an observability maturity model
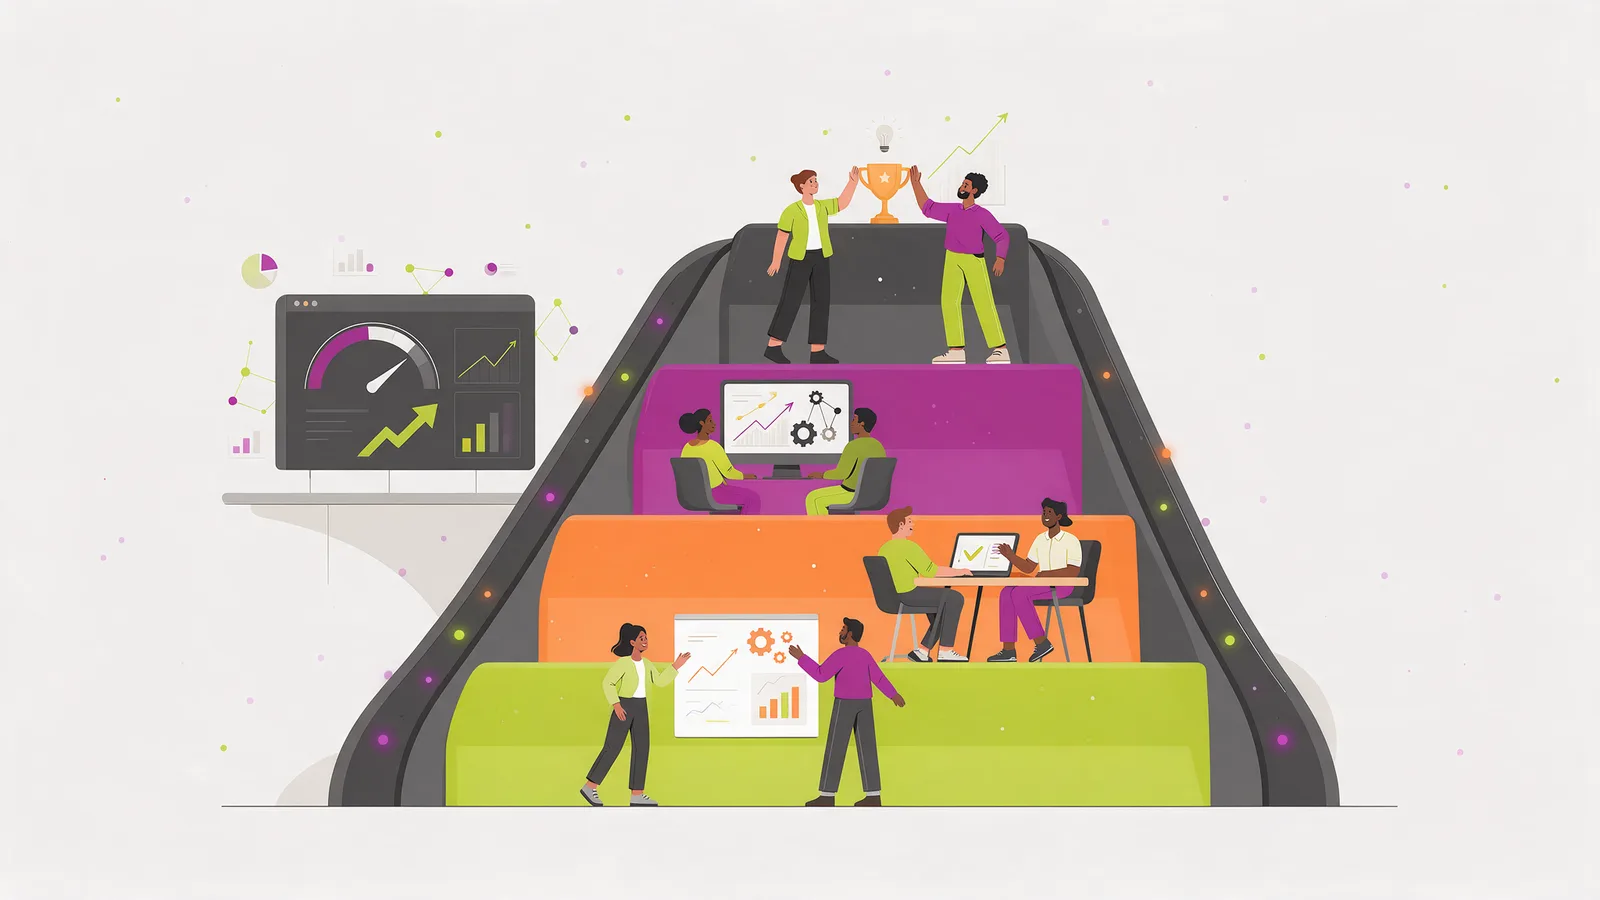
There is no single international standard for observability maturity. Models published by vendors and communities use their own scales. The scale below is a Maturity Lab synthesis built on concepts from DORA, OpenTelemetry and Google’s site reliability engineering book. It follows the staircase logic used in management maturity models.
| Level | Name | What characterizes the level |
|---|---|---|
| 1 | Reactive | Users discover failures; each team reads server logs when something breaks |
| 2 | Monitored | Dashboards and alerts for known conditions, such as availability and resource usage |
| 3 | Instrumented | Traces, metrics and logs standardized and correlated across services |
| 4 | Objective-driven | Service level indicators and objectives agreed with the business and used to prioritize |
| 5 | Observable | The team investigates new failures without new instrumentation and uses the learning to prevent incidents |
Each level builds on the previous one. An organization cannot set reliable service level objectives if it does not yet collect data in a standard way across services.
Did you know? Google’s site reliability engineering book defines the four golden signals of monitoring: latency, traffic, errors and saturation. The same chapter recommends that every page sent to a person be actionable (sre.google).
Signs that reveal the current level
Some observable signs indicate the likely level before any questionnaire:
- Level 1 signs: the first incident warning comes from support or from a customer; there is no shared dashboard; investigation depends on direct server access.
- Level 2 signs: dashboards and alerts exist, but each team uses its own tool; the team receives alerts that require no action and starts to ignore them.
- Level 3 signs: services emit data in the same standard; a request can be followed end to end; correlating a log, a metric and a trace takes minutes, not hours.
- Level 4 and 5 signs: each critical service has an indicator and a service level objective agreed with the business; error budget consumption sets the priority between fixes and new features; post-incident reviews produce recorded changes.
Buying a tool does not set the level. A complete platform with no instrumentation standard and no alert owner keeps the organization at level 2. DORA lists as a pitfall having a single monitoring person or dedicated team solely responsible for the system (dora.dev).
How to assess observability maturity
The assessment turns team perception into a score by dimension and an action plan.
In practice: 6 steps for the assessment
- Define the scope. Choose the services that are critical to the business. Assessing every system in the first round produces an average with no use.
- Define the dimensions. Use dimensions such as instrumentation, collection and storage, alerting and incident response, service level objectives, culture and responsibilities, and use of data in decisions.
- Collect answers from different roles. Development, operations, support and product management answer the same questionnaire. Divergence between roles is a finding.
- Require evidence. Every positive answer points to a dashboard, a configured alert, a post-incident report or a documented objective. Without evidence, the practice counts as not implemented.
- Calculate the score by dimension. The overall level is capped by the weakest dimension. Advanced instrumentation with no alert owner does not sustain level 3.
- Build the next-level plan. Select three to five practices from the next step, with an owner and a deadline, and repeat the assessment once the practices are in use.
Common mistakes in observability progress
The first mistake is treating observability as a tooling project. The tool collects data; the level depends on who uses the data, with which question and for which decision.
The second mistake is measuring everything. Too many alerts create fatigue, and the team stops reacting to the alert that matters. The criterion in Google’s site reliability engineering book helps: an alert that requires no human action should not wake anyone up.
The third mistake is assessing observability apart from management. Service level objectives depend on priorities set by leadership, and post-incident reviews depend on a blameless culture. The same reasoning applies to the test maturity model: when the technical assessment reveals gaps in priorities and responsibilities, a business maturity assessment helps locate the origin.
Frequently asked questions
Does observability replace monitoring?
No. Monitoring is still needed for known conditions, such as availability and capacity. Observability extends the team’s ability to investigate failures nobody anticipated.
Is OpenTelemetry required to reach level 3?
No. Level 3 requires standardized instrumentation correlated across services. OpenTelemetry is an open standard that makes this easier, but the assessment checks the practice, not the tool brand.
Do small teams need an observability maturity model?
Yes, at a smaller scale. A small team can start with the four golden signals on critical services and a simple rule of actionable alerts. The model sets the order of practices and avoids investing in tools too early.